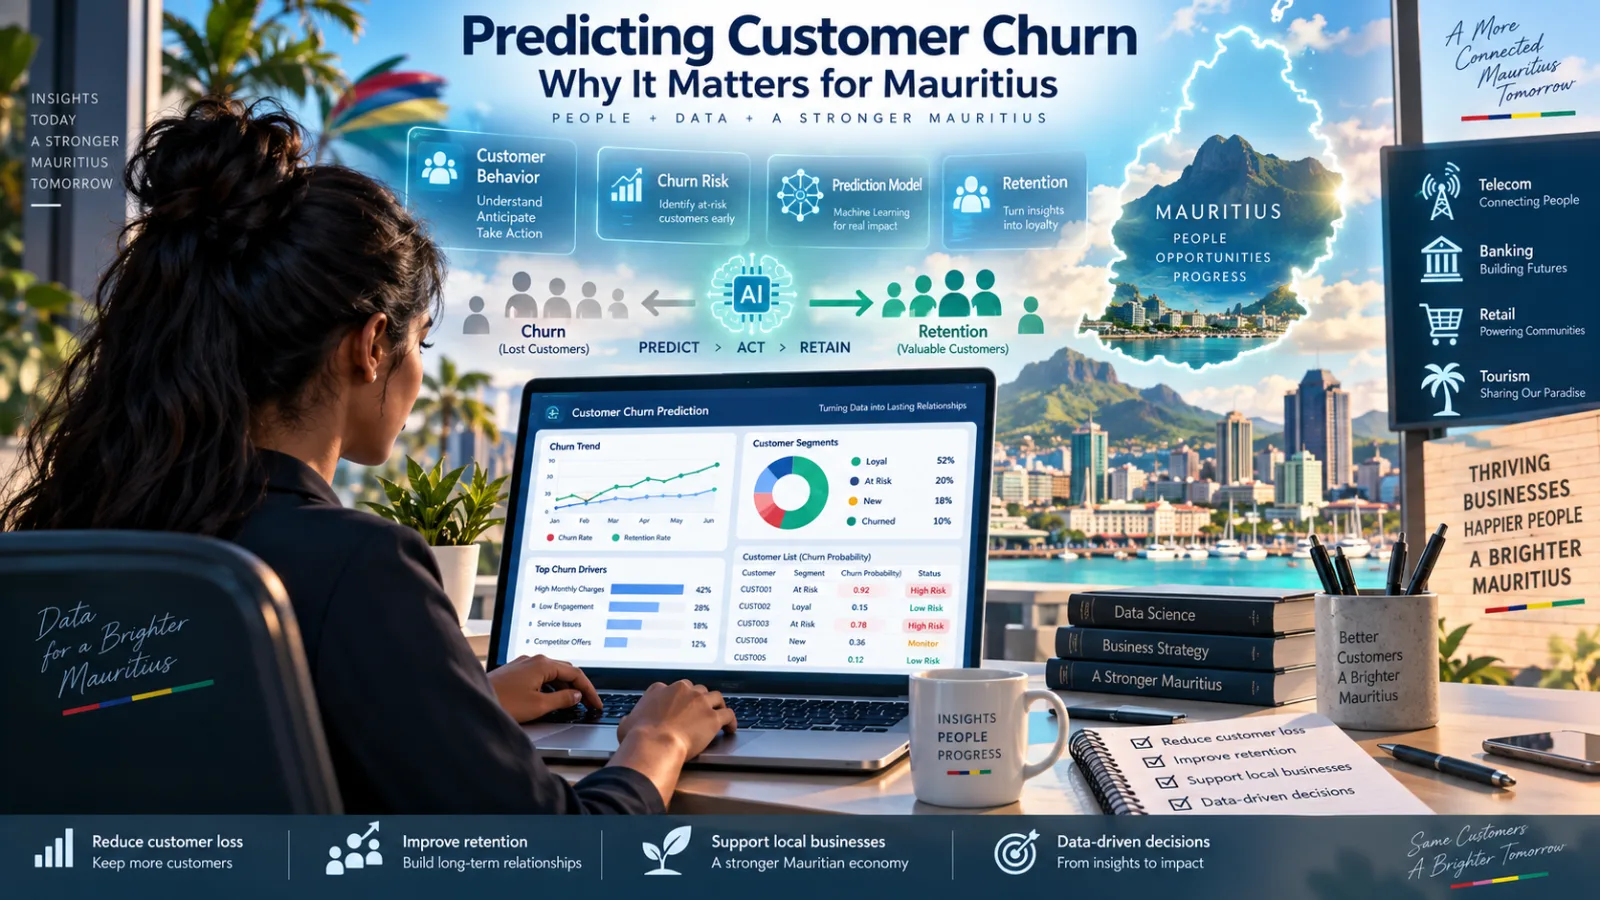
A machine-learning model does not need near-perfect accuracy to create business value.
That was probably the most important lesson from my final assignment for GCI World 2026, organised by the University of Tokyo's Matsuo-Iwasawa Lab.
For the project, I worked with a telecom churn dataset and took the role of a consultant advising an anonymous operator, which I referred to as Company A.
The company had around 100,000 customers, plenty of historical data, and no existing in-house machine-learning capability.
The business problem was straightforward:
Can we identify customers who are likely to leave early enough to do something about it?
The answer turned out to be yes.
But the interesting part was not simply building a classifier.
It was turning its predictions into a business decision.
The First Number Was Hard to Ignore
The first stage was exploratory analysis.
The data came from two main sources: one containing usage and billing information, and another containing customer account and device information.
After combining them, one figure immediately stood out:
49.6% of customers had churned within two months of the observation date.
That is an extremely high churn rate.
At that point, the task stopped being an abstract machine-learning exercise.
If half of a customer base is disappearing within such a short period, retention becomes a major commercial problem.
The next question was:
What separates customers who stay from customers who leave?
Three Signals Stood Out
The analysis revealed several patterns, but three were particularly useful.
Older Handsets Were Associated with Higher Churn
Churn increased steadily as handset age increased.
Customers with phones less than six months old had a churn rate of around 42%.
For customers using devices more than two years old, that figure increased to around 58%.
That does not prove that an old handset causes a customer to leave.
But it suggests that device age contains useful information about customer risk.
A subscriber with an ageing device may be more receptive to a competitor's handset offer, or may simply be reaching a natural decision point about whether to remain with the operator.
Falling Usage Was Another Warning Sign
A sharp decline in recent usage was also associated with churn.
This makes intuitive business sense.
A customer often begins disengaging before formally leaving.
Calls decline.
Data usage changes.
Activity becomes less regular.
The eventual churn event may therefore be the final step in a behavioural change that started weeks earlier.
That creates an opportunity.
If declining engagement can be detected early enough, the operator may still have time to intervene.
The Middle of the Customer Lifecycle Was Risky
Churn was also particularly high among customers with approximately 12 to 24 months of tenure.
This is useful because churn is not always evenly distributed across the customer lifecycle.
A new customer, an established long-term customer and someone around the second year of their relationship with the operator may behave quite differently.
The model needed to capture those differences rather than treating every subscriber as equally likely to leave.
Building the Baseline
Before using a more flexible model, I trained a logistic regression classifier.
That gave me a baseline.
This step is important because a more complicated model should not automatically be assumed to be better simply because it is more sophisticated.
The logistic regression reached a ROC-AUC of 0.61.
I then trained a HistGradientBoostingClassifier using scikit-learn.
On a held-out test set of 20,000 customers, the gradient boosting model achieved:
ROC-AUC: 0.69
At first glance, 0.69 does not look spectacular.
And it isn't.
It would be misleading to present it as an exceptionally accurate churn model.
But that raised a more interesting question:
Does the model actually need to perfectly classify every customer?
For this use case, the answer is no.
Prediction Wasn't the Real Objective
Imagine a telecom operator has 100,000 customers.
It cannot realistically provide expensive retention incentives to everyone.
That would destroy the economics of the programme.
What the company really needs is a way to answer:
Which customers should we contact first?
That changes how the model should be evaluated.
Instead of focusing only on the classification threshold, I ranked customers by their predicted probability of churn.
The results were much more commercially interesting.
Among customers in the highest-risk 10%, approximately:
79% actually churned.
At the other end of the ranking, churn among the lowest-risk group was only around:
20%.
That separation is valuable.
The model does not need to predict every churn event correctly.
It needs to push genuinely risky customers toward the top of the list.
Why Ranking Matters
Suppose the company can afford to target only the highest-risk 20% of customers.
The model allows those retention offers to be concentrated where they are much more likely to matter.
Under the analysis, roughly 7 out of 10 customers in that targeted group were customers who would otherwise churn.
Without a model, the company might:
- Contact customers randomly
- Target broad demographic groups
- Send retention offers to everyone
- React only after customers request cancellation
All of those approaches waste resources.
A risk model gives the company another option:
Prioritise customers based on behavioural evidence.
That is where a moderate ROC-AUC can still translate into significant business value.
From Model to Business Proposal
A prediction alone is not a retention strategy.
The operator still needs to decide what to do with it.
My proposal was called:
Device Refresh & Save
The concept was simple.
Once a month, the operator scores its customer base using the churn model.
Customers with the highest predicted risk are selected for intervention.
But instead of giving everyone the same offer, the incentive would be matched to the likely reason for churn.
For example:
Older handset → device upgrade offer
Changing usage → better-matched mobile plan
Long-standing customer → loyalty reward
This turns churn prediction into a decision system:
Customer data → Risk score → Likely driver → Targeted retention offer
That is much more useful than simply displaying a red "high-risk" label on a dashboard.
Estimating the Commercial Value
I then built a simple financial case around the retention programme.
Under deliberately conservative assumptions, the proposed programme would protect approximately:
$3.1 million per year
at an estimated annual cost of around:
$0.4 million
That represents roughly a:
6.7× return
The exact number obviously depends on assumptions such as customer value, campaign cost and how many targeted customers can actually be retained.
The purpose of the calculation was not to claim that $3.1 million was guaranteed.
It was to answer a more practical management question:
Is this problem economically large enough to justify building and operating the system?
The analysis suggested that it was.
Then I Asked a Different Question
The original dataset was not from Mauritius.
But once the analysis was complete, I wanted to know whether the underlying idea could make sense in the Mauritian telecom market.
That required separating two things.
The trained model cannot simply be copied into a Mauritian operator and assumed to work.
The methodology, however, can.
That distinction is important.
Why Churn Matters in Mauritius
Mauritius is a highly mature mobile market.
When most potential customers already have mobile service, growth increasingly depends on factors such as:
- Retaining existing subscribers
- Increasing customer value
- Winning customers from competitors
- Reducing unnecessary acquisition costs
That makes churn strategically important.
In a market where switching is relatively easy, losing an existing customer can be much more expensive than retaining one.
The high share of prepaid subscriptions makes this particularly interesting.
A prepaid customer does not necessarily have a long contractual commitment preventing them from changing operator.
That means behavioural signals can become especially important.
The operator may not receive an explicit cancellation request.
The customer may simply reduce usage, stop recharging and move elsewhere.
By the time this is obvious in traditional reporting, the relationship may already be lost.
Portability Changes the Equation Further
Mobile number portability makes switching even easier because customers can change provider without giving up their existing phone number.
That removes one of the practical inconveniences that can discourage switching.
From an analytics perspective, that increases the value of identifying churn risk before the customer makes the decision to leave.
The operator that detects weakening engagement first has an opportunity to respond.
The operator that notices only after the customer has gone is already too late.
Translating the Idea to a Mauritian Operator
For the assignment, I created a hypothetical application of the same targeting strategy to a Mauritian operator of roughly Emtel's scale.
Using explicitly stated assumptions for customer value, campaign cost, targeting and retention effectiveness, the model suggested that a similar programme could potentially protect approximately:
Rs 31 million per year
for an estimated:
Rs 9.4 million in campaign spending.
Again, these figures are scenario estimates, not forecasts.
A real operator would need to replace those assumptions with its own:
- Subscriber base
- Revenue per user
- Churn rate
- Retention costs
- Offer acceptance rate
- Customer lifetime value
That is how the proof-of-concept would become an actual business case.
What Would Need to Change for Mauritius?
The biggest limitation is straightforward:
The original dataset is not Mauritian.
Customer behaviour varies by market.
Pricing is different.
Prepaid behaviour is different.
Promotions differ.
Competitor behaviour differs.
Network quality differs.
Even the meaning of certain usage patterns may be different.
A production system in Mauritius would therefore need to be trained on local historical customer data.
That might include variables such as:
- Recharge behaviour
- Mobile data consumption
- Voice usage
- Package purchases
- Device age
- Customer tenure
- Complaints
- Network experience
- Previous promotional responses
The exact features would depend on what an operator actually records.
The model would then need to be validated on customers it had not previously seen.
Only after that would I trust its scores for a real retention campaign.
A Better Model Isn't Always the Biggest Opportunity
There would also be plenty of scope for improving the model itself.
More feature engineering could be explored.
Different boosting algorithms could be compared.
Hyperparameters could be tuned.
Additional behavioural variables might improve predictive performance.
But one thing became clear while doing the assignment:
Going from no model to a useful model may create more business value than going from a useful model to a slightly better one.
An organisation with no churn prediction system does not necessarily need the most sophisticated algorithm available.
It needs a model that is reliable enough to improve a real decision.
That is a very different objective.
The Real Product Is the Intervention
Another lesson was that machine learning is only one component of the solution.
A churn model that produces a probability score and then sits in a notebook creates very little value.
The useful system is:
Data → Prediction → Decision → Action → Measurement
After customers receive retention offers, the company also needs to measure what happened.
Did the targeted customers stay?
Which offer worked?
Which offers were too expensive?
Which customer segments responded?
Did retention improve because of the campaign, or would those customers have stayed anyway?
Eventually, that feedback should return to the modelling process.
That is when churn prediction becomes an operational system rather than a university exercise.
What I Took Away from the Project
I started the assignment thinking mainly about classification.
I finished it thinking much more about decision-making.
A ROC-AUC score tells me something about model performance.
It does not tell a telecom executive what to do on Monday morning.
For that, the analysis has to move further.
Who should be contacted?
How many customers can we afford to target?
What should each person be offered?
How much revenue might be protected?
How do we measure whether the intervention actually worked?
Those questions sit at the intersection of data science and business strategy.
And that was the part of the assignment I found most valuable.
The goal was never simply to predict who might leave.
The goal was to identify the customers where an operator still had enough time — and enough information — to give them a reason to stay.
Tools used: Python · pandas · scikit-learn · Google Colab
Join the conversation
Loading comments…